
Evaluation · Research
Use embedding leaderboards to shortlist, not to sign off
Choose retrieval models against local language, identifiers, and operating constraints.
Read the task behind the score
MTEB and MMTEB organize embedding evaluation across different tasks and languages. An overall rank is therefore a starting point, not a purchase decision for a specific company. Check whether the relevant retrieval task and language are represented. A model that is strong on broad semantic similarity may still miss a specialized abbreviation or a product reference that your employees consider obvious.
Create a company retrieval challenge
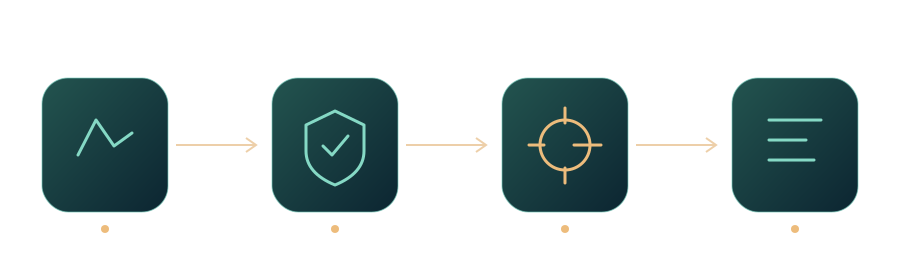
For an illustrative consultancy, include English procedures, Chinese questions, short names, and retired versions as distractors. Label the passages that should be retrieved. Keep generation out of the first comparison so a language model cannot compensate for a weak retriever. Evaluate whether staff can reach the correct evidence with acceptable latency. Keep a few difficult cases hidden until the shortlist has been chosen.
Workflow at a glance
Include migration cost
Changing embeddings may require reprocessing the corpus and maintaining a compatible index. Estimate compute, storage, update time, and engineering effort before celebrating a small score gain. Check model license and hosting requirements using current official terms. A compact model that meets your actual acceptance tests may be operationally preferable to a larger alternative; the choice depends on your service envelope, not a general rule that smaller is better.
Record the decision boundary
Write down why the selected model won, which tasks remain weak, and when to revisit the decision. Keep the test set and index configuration with the handover materials. New languages, document formats, or data volumes can change the comparison. Public leaderboards are valuable research infrastructure; treating them as local certification wastes the opportunity to learn what your own retrieval system actually needs.
A migration rehearsal
Before switching the production embedder, build a parallel test index and document rollback. Verify identifiers, language behavior, citations, and refresh operations. The winning model must fit the whole retrieval service; an attractive benchmark gain is insufficient if routine updates or recovery become unreliable.
Sources and further reading
- MTEB: Massive Text Embedding BenchmarkMTEB: Massive Text Embedding BenchmarkHugging Face · Research source ·
- MMTEB: Massive Multilingual Text Embedding BenchmarkMMTEB: Massive Multilingual Text Embedding BenchmarkMMTEB authors / arXiv · Research source ·
Editorial approach
AI-assisted original writing, checked against linked public sources. Practical recommendations and illustrative scenarios are editorial analysis, not reported client results. Source dates and product details may differ from this collection’s preparation date.